Working paper, 2026
arXiv / demo
An AI-assisted workflow replicating hundreds of political science studies finds full-paper reproducibility rose from 29.6% to 79.8% after journals adopted DA-RT. abstract
I am an Associate Professor, with tenure, in the Department of Political Science at Stanford University. I work in political methodology (applied statistics) and comparative politics. My current research interests center on causal inference with panel data, applications of AI to social science research, and comparative politics with a focus on China.
I received a PhD in Political Science from MIT in 2016, an MA in Economics from the China Center for Economic Research (CCER) at Peking University in 2010, and a BA in Economics from Fudan University in 2007. I taught at UC San Diego from 2016 to 2019. I am an associate director of the Stanford Causal Science Center (SC2).
yiqingxu [at] stanford.edu / CV / Google Scholar / GitHub
Selected papers on causal inference with panel data, AI for social science, and Chinese politics. All papers.
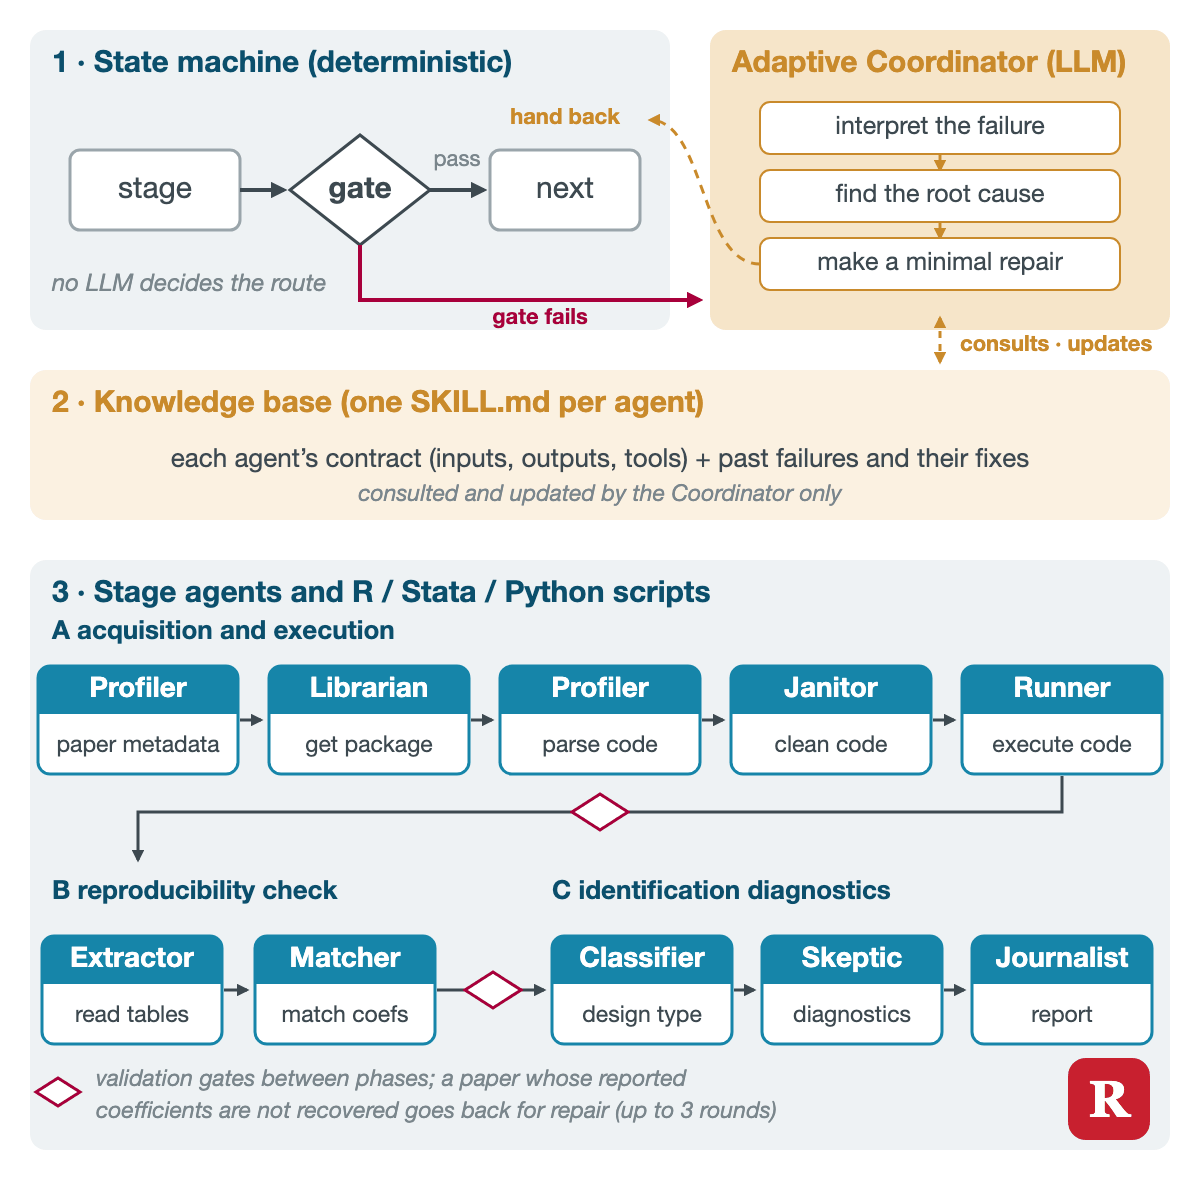
An AI-assisted workflow replicating hundreds of political science studies finds full-paper reproducibility rose from 29.6% to 79.8% after journals adopted DA-RT. abstract
Computational reproducibility is central to scientific credibility, yet verifying published results at scale remains costly. We develop an AI-assisted workflow for automated full-paper replication---retrieving materials, reconstructing environments, executing code, and matching outputs to point estimates reported in regression tables. We define a universe of all empirical and quantitative papers from the three top political science journals (2010--2025) and measure stated data availability using automated extraction. For a stratified sample of 384 studies, we apply the workflow to conduct full-paper replication, totaling 3,382 empirical models. We find that journal verification requirements, combined with data archiving mandates, drive reproducibility: the full-paper reproducibility rate rises from 29.6% before DA-RT adoption to 79.8% after, and conditional on accessible replication packages, 94.4% of papers are fully reproducible (237/251). As a secondary application, we apply standardized IV diagnostics to 92 studies (215 specifications), illustrating how automated execution enables systematic reanalysis across heterogeneous empirical settings.
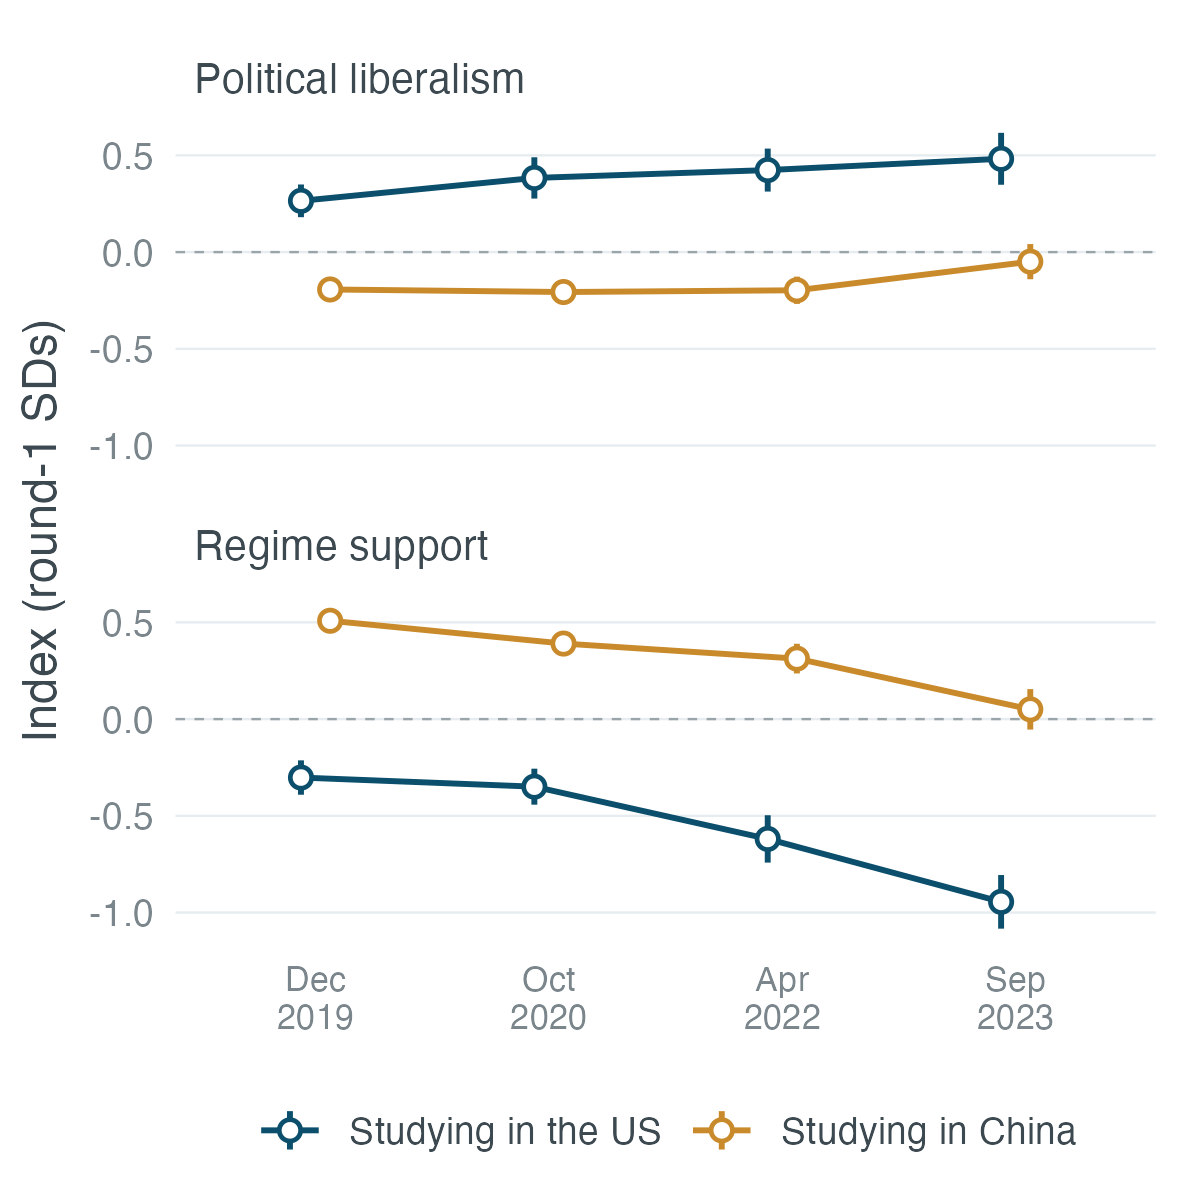
Chinese students who go to the US are more liberal before they leave, and ideology stays stable through college wherever they study. abstract
Theories of democratic diffusion predict that exposure to liberal democracies fosters support for political liberalism, while recent studies on Chinese overseas students suggest studying abroad generates backlash against liberal values. Using a unique four-year longitudinal dataset of nearly 1,000 Chinese college students in China and the United States, we examine how studying abroad shapes students’ ideology, attitudes, and identity. Our findings challenge both perspectives. Students who study in the United States are already more politically liberal, market-oriented, and cosmopolitan, and less nationalistic than their peers upon departure, underscoring the importance of selection. Ideological preferences remain remarkably stable throughout college, regardless of location. However, support for China’s political system and affective identification with Chinese national identity declines among students in both countries from 2022 to 2023, with a greater decline among students in the United States. These results show that selection, home-country shocks, and host-country context jointly shape overseas students’ political attitudes.
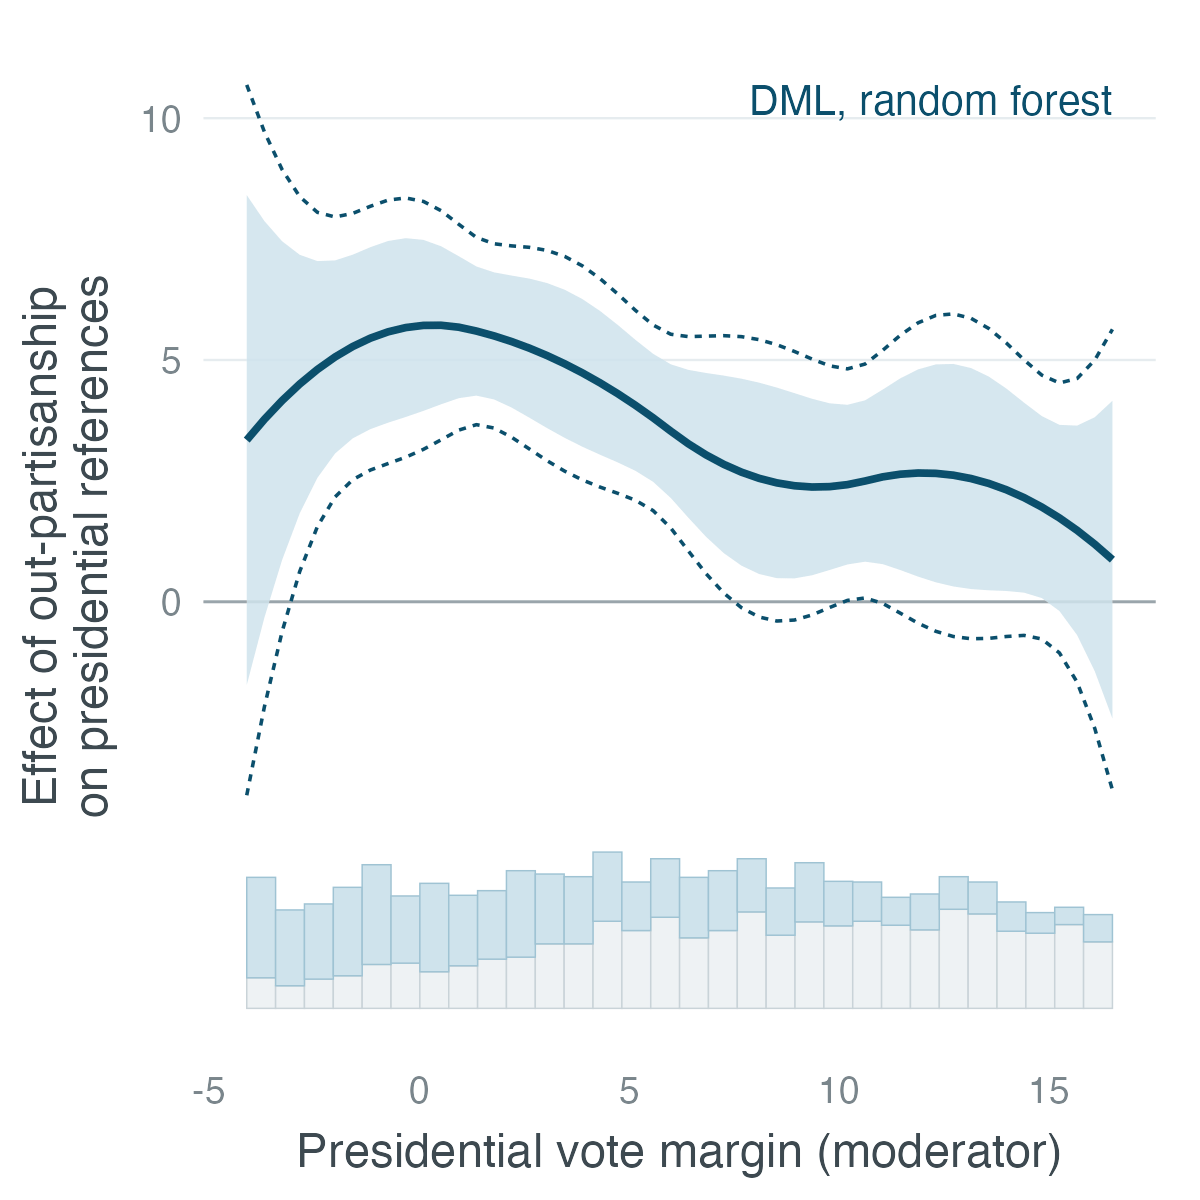
Kernel, AIPW-Lasso and double machine learning estimators, all in the interflex R package, estimate how treatment effects vary with a moderating variable. abstract
This Element offers a practical guide to estimating conditional marginal effects—how treatment effects vary with a moderating variable—using modern statistical methods. Commonly used approaches, such as linear interaction models, often suffer from unclarified estimands, limited overlap, and restrictive functional forms. This guide begins by clearly defining the estimand and presenting the main identification results. It then reviews and improves upon existing solutions, such as the semiparametric kernel estimator, and introduces robust estimation strategies, including augmented inverse propensity score weighting with Lasso selection (AIPW-Lasso) and double machine learning (DML) with modern algorithms. Each method is evaluated through simulations and empirical examples, with practical recommendations tailored to sample size and research context. All tools are implemented in the accompanying interflex package for R.
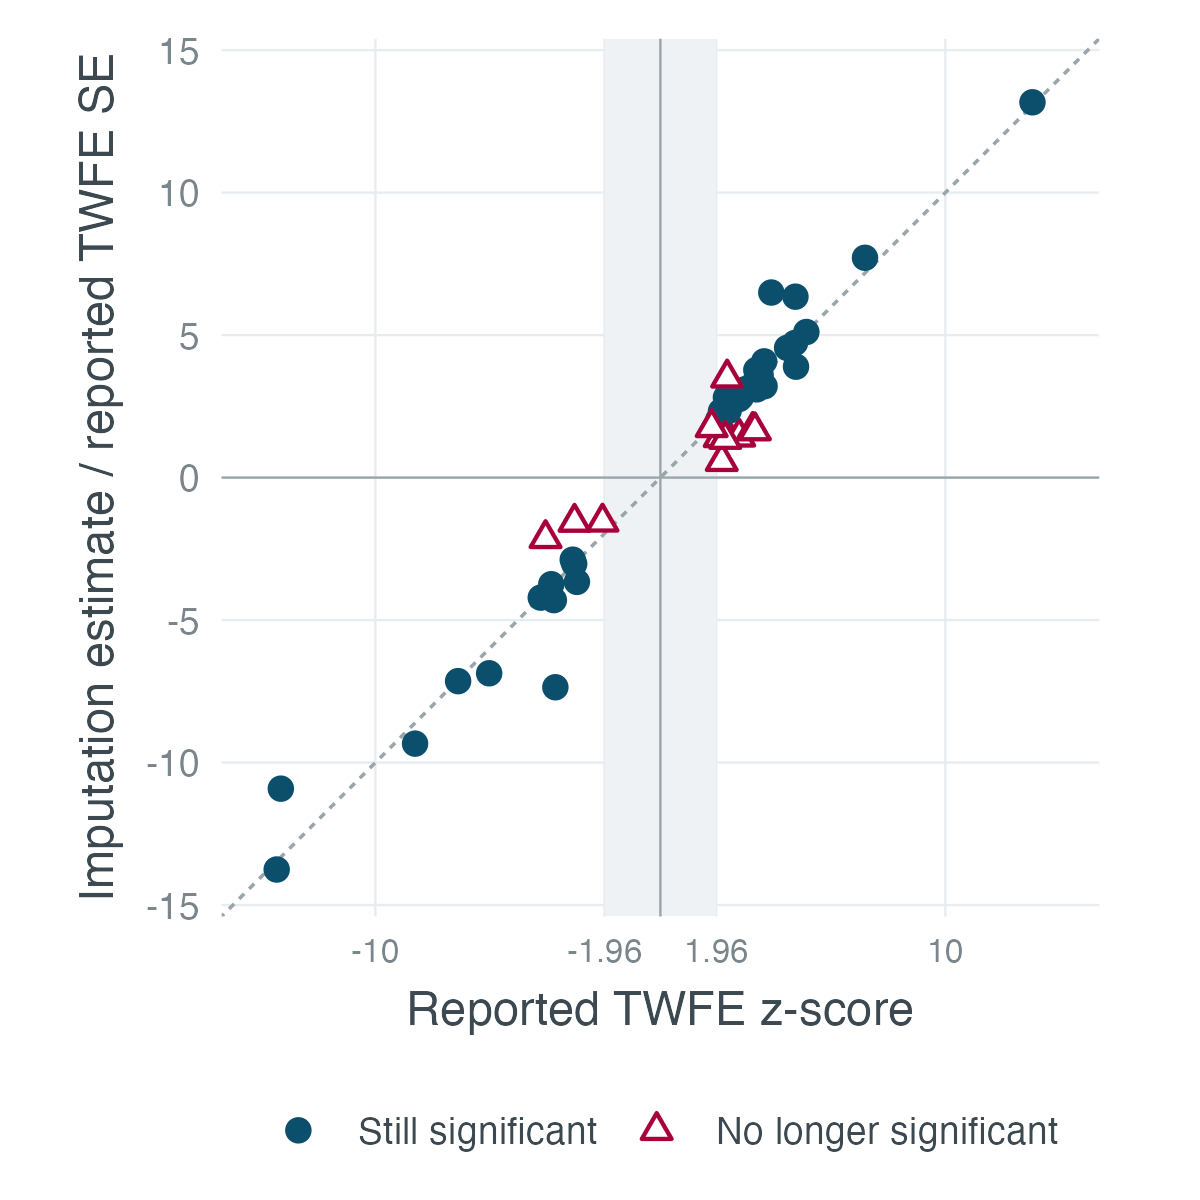
In 49 reanalyzed panel studies, modern-DID estimators give similar but highly variable results, and many studies lack parallel-trends evidence or power. abstract
Two-way fixed effects (TWFE) models are widely used in political science to establish causality, but recent methodological discussions highlight their limitations under heterogeneous treatment effects (HTE) and violations of the parallel trends (PT) assumption. This growing literature has introduced numerous new estimators and procedures, causing confusion among researchers about the reliability of existing results and best practices. To address these concerns, we replicated and reanalyzed 49 studies from leading journals using TWFE models for observational panel data with binary treatments. Using six HTE-robust estimators, diagnostic tests, and sensitivity analyses, we find: (i) HTE-robust estimators yield qualitatively similar but highly variable results; (ii) while a few studies show clear signs of PT violations, many lack evidence to support this assumption; and (iii) many studies are underpowered when accounting for HTE and potential PT violations. We emphasize the importance of strong research designs and rigorous validation of key identifying assumptions. (Please see the Erratum , which addresses a typesetting error in the published article.)
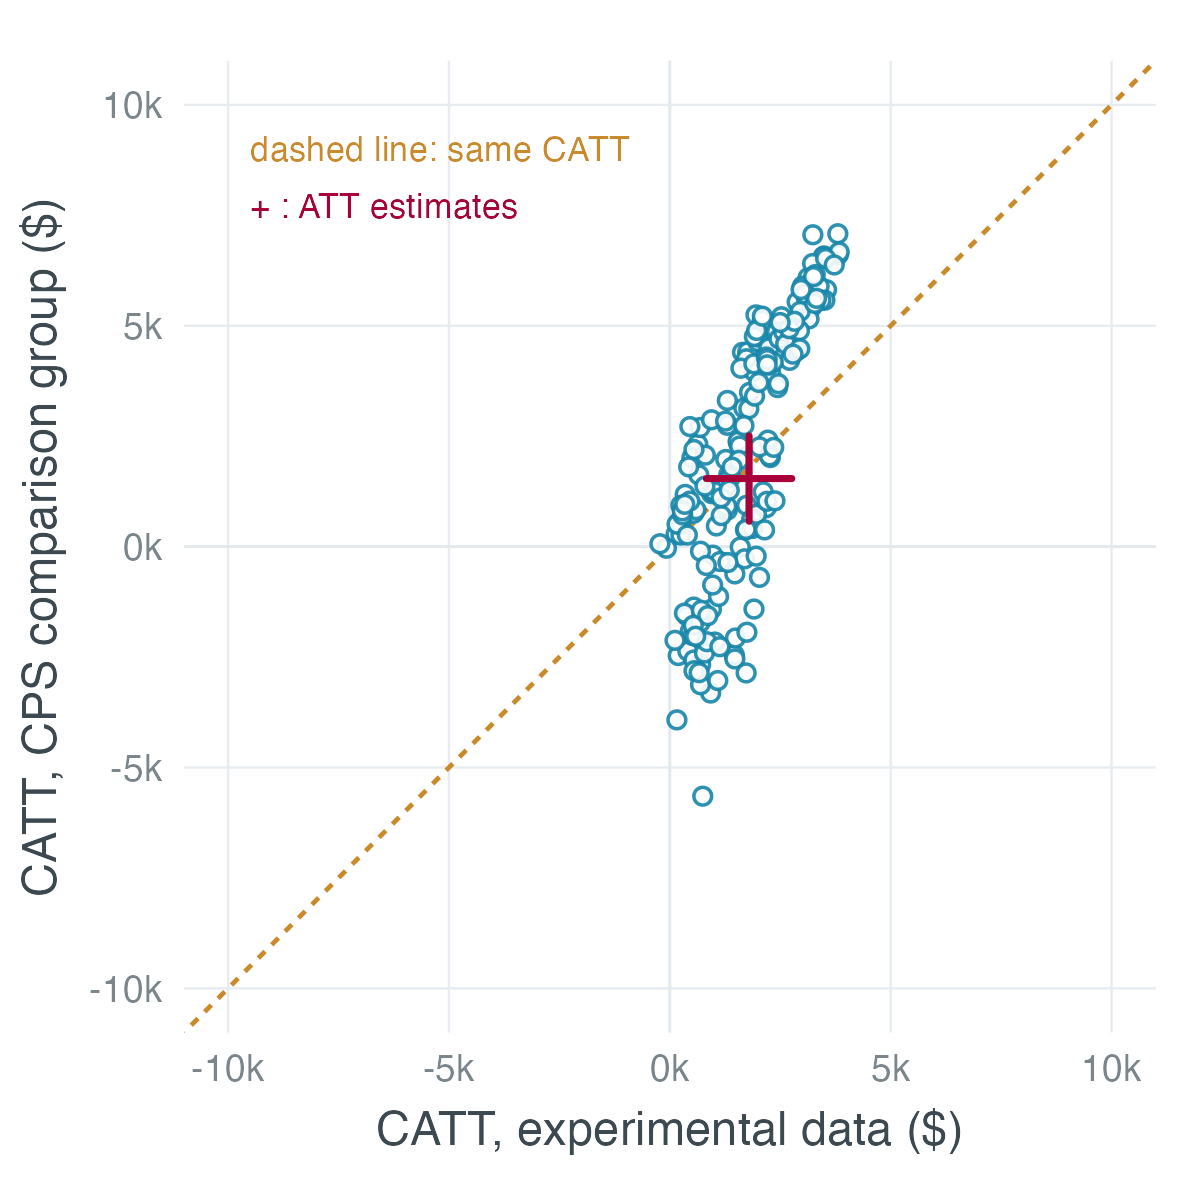
With enough covariate overlap, modern methods give stable estimates on the LaLonde data, but only validation exercises show whether they are causal. abstract
In 1986, Robert LaLonde published an article comparing nonexperimental estimates to experimental benchmarks (LaLonde 1986). He concluded that the nonexperimental methods at the time could not systematically replicate experimental benchmarks, casting doubt on their credibility. Following LaLonde's critical assessment, there have been significant methodological advances and practical changes, including (i) an emphasis on the unconfoundedness assumption separated from functional form considerations, (ii) a focus on the importance of overlap in covariate distributions, (iii) the introduction of propensity score-based methods leading to doubly robust estimators, (iv) methods for estimating and exploiting treatment effect heterogeneity, and (v) a greater emphasis on validation exercises to bolster research credibility. To demonstrate the practical lessons from these advances, we reexamine the LaLonde data. We show that modern methods, when applied in contexts with sufficient covariate overlap, yield robust estimates for the adjusted differences between the treatment and control groups. However, this does not imply that these estimates are causally interpretable. To assess their credibility, validation exercises (such as placebo tests) are essential, whereas goodness-of-fit tests alone are inadequate. Our findings highlight the importance of closely examining the assignment process, carefully inspecting overlap, and conducting validation exercises when analyzing causal effects with nonexperimental data.
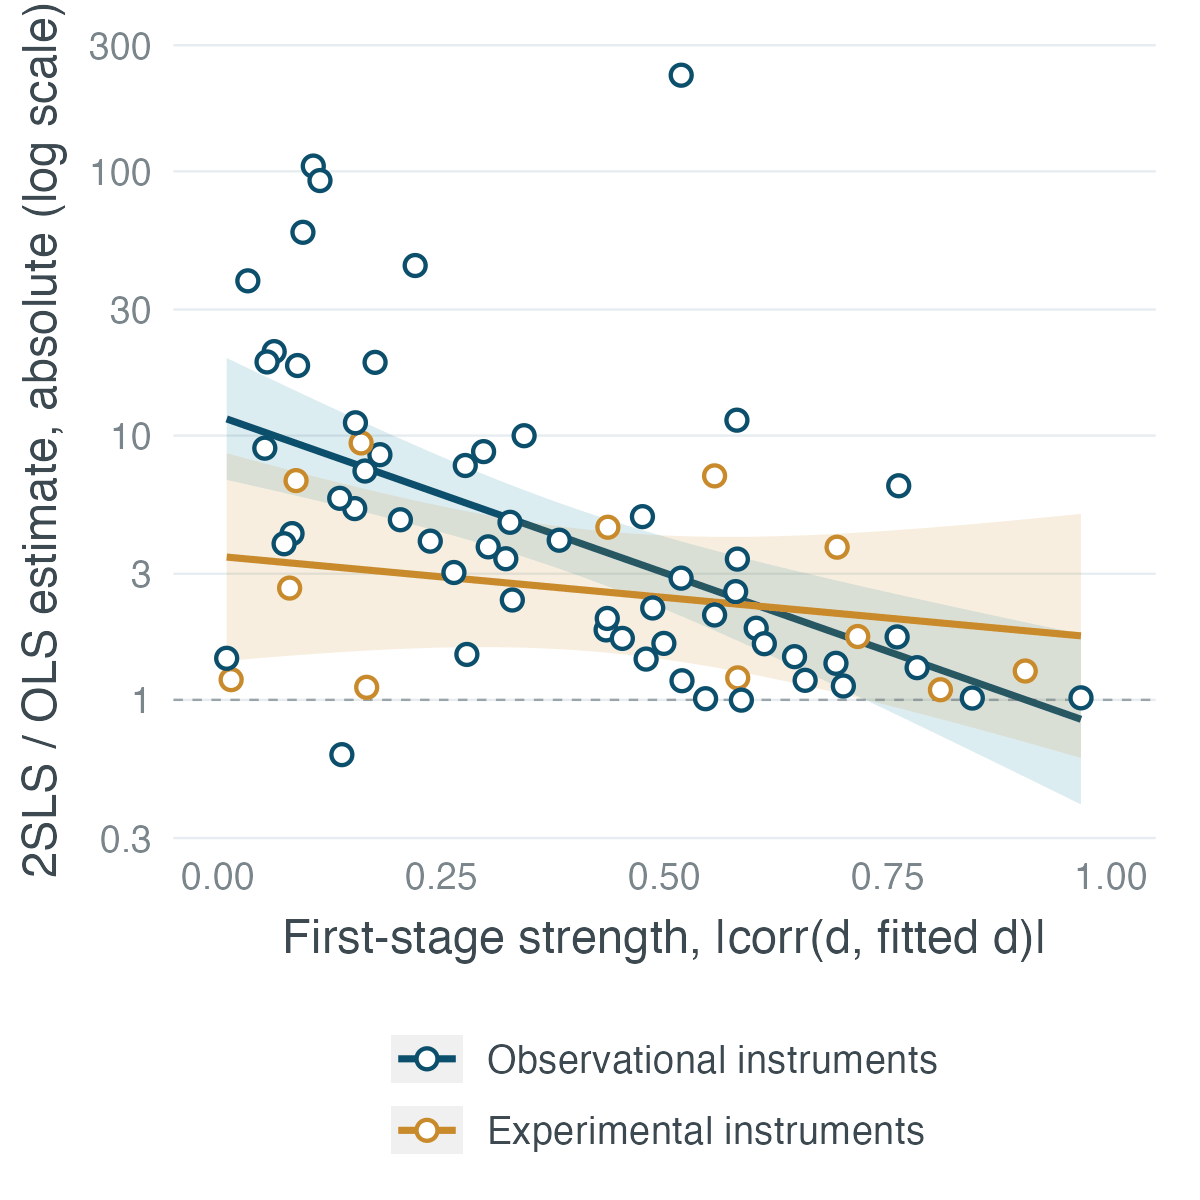
In 67 replicated instrumental variable studies, instrument strength is often overestimated, uncertainty is understated, and 2SLS estimates usually exceed OLS estimates. abstract
Instrumental variable (IV) strategies are widely used in political science to establish causal relationships, but the identifying assumptions required by an IV design are demanding, and assessing their validity remains challenging. In this paper, we replicate 67 articles published in three top political science journals from 2010-2022 and identify several concerning patterns. First, researchers often overestimate the strength of their instruments due to non-i.i.d. error structures such as clustering. Second, the commonly used t -test for two-stage-least-squares (2SLS) estimates frequently underestimates uncertainties, resulting in uncontrolled Type-I errors in many studies. Third, in most replicated studies, 2SLS estimates are significantly larger than ordinary-least-squares estimates, with their ratio negatively correlated with instrument strength in studies with non-experimentally generated instruments, suggesting potential violations of unconfoundedness or the exclusion restriction. We provide a checklist and software to help researchers avoid these pitfalls and improve their practice.

R and Stata packages for panel data and other causal inference problems. All software.
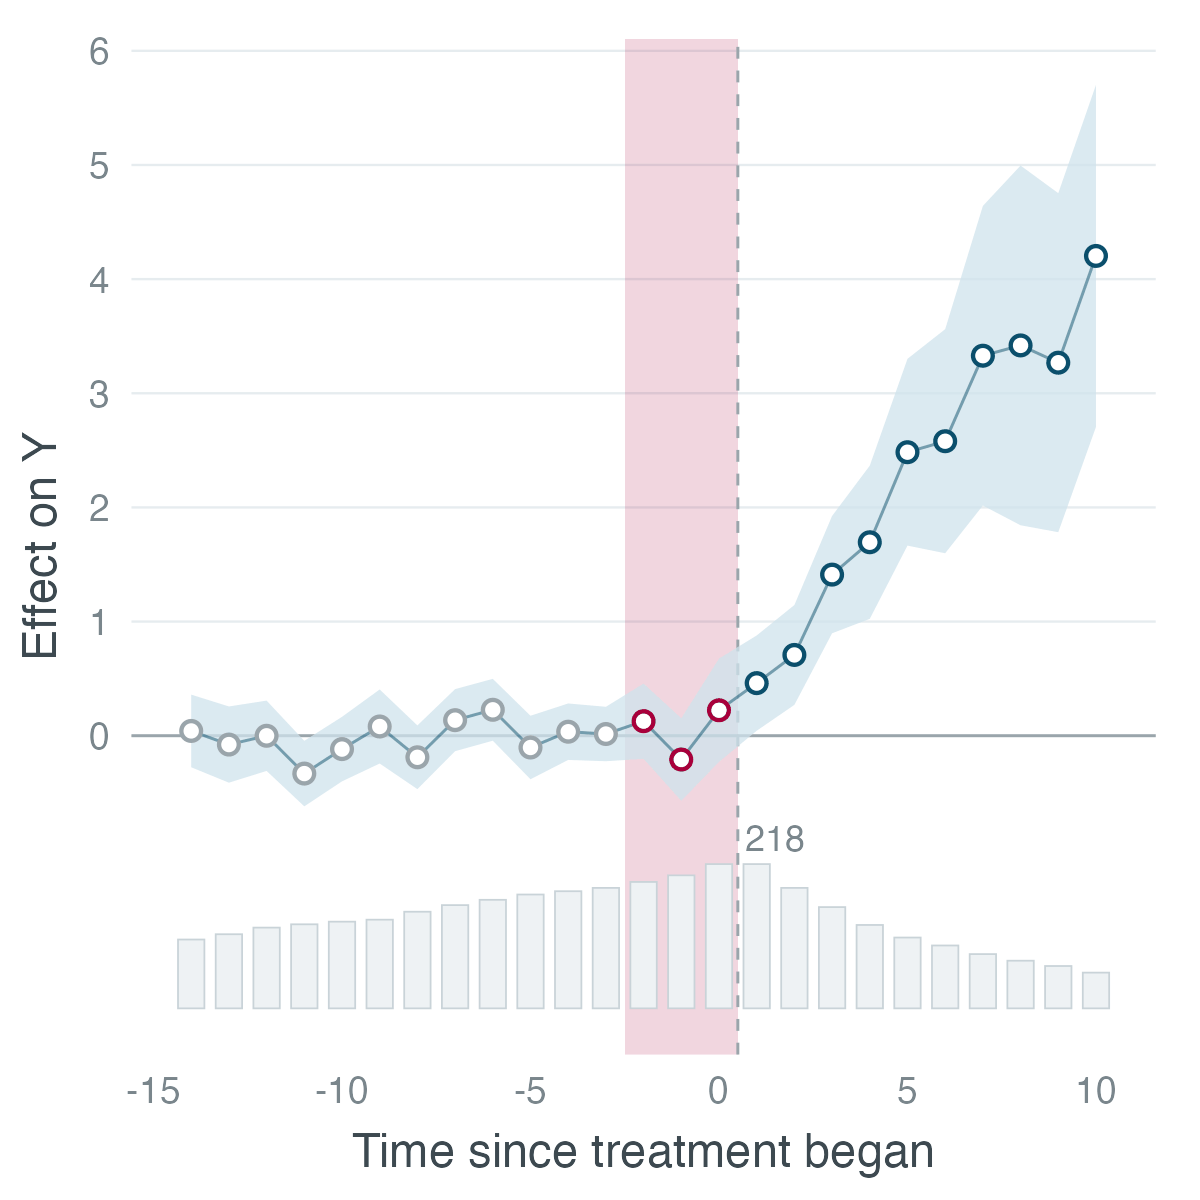
fect implements a group of counterfactual estimators for causal inference using panel data with binary treatments, including interactive fixed effects and matrix completion methods. It also offers several diagnostic tests, such as a placebo test (for no pre-trends).
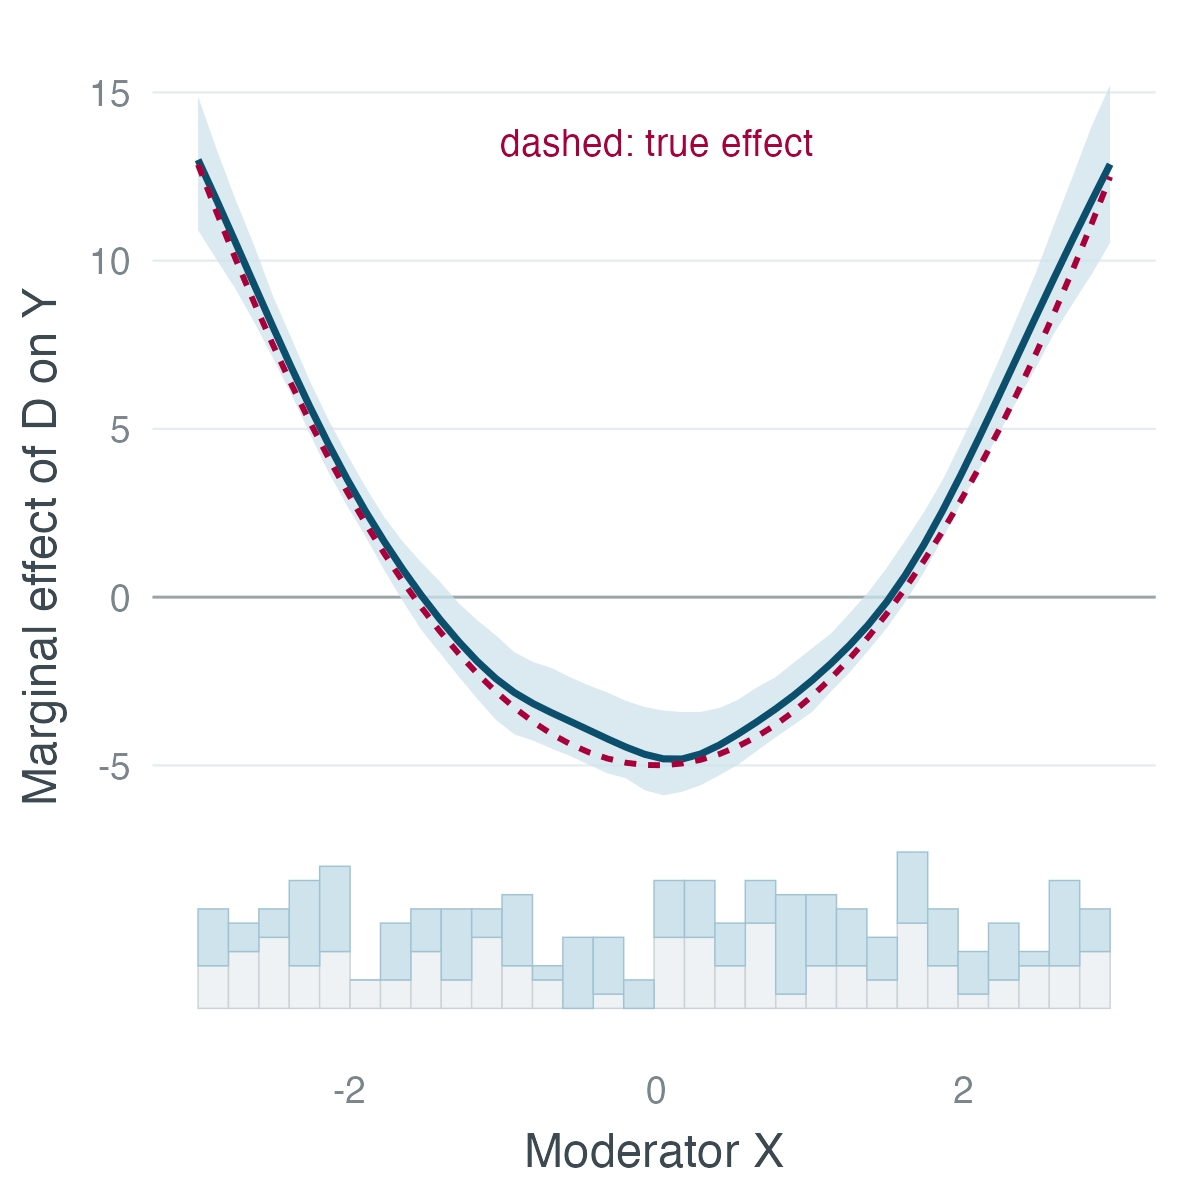
interflex estimates and visualizes conditional marginal effects and performs diagnostics. It is the winner of the Best Statistical Software Award from the Society of Political Methodology for 2023.
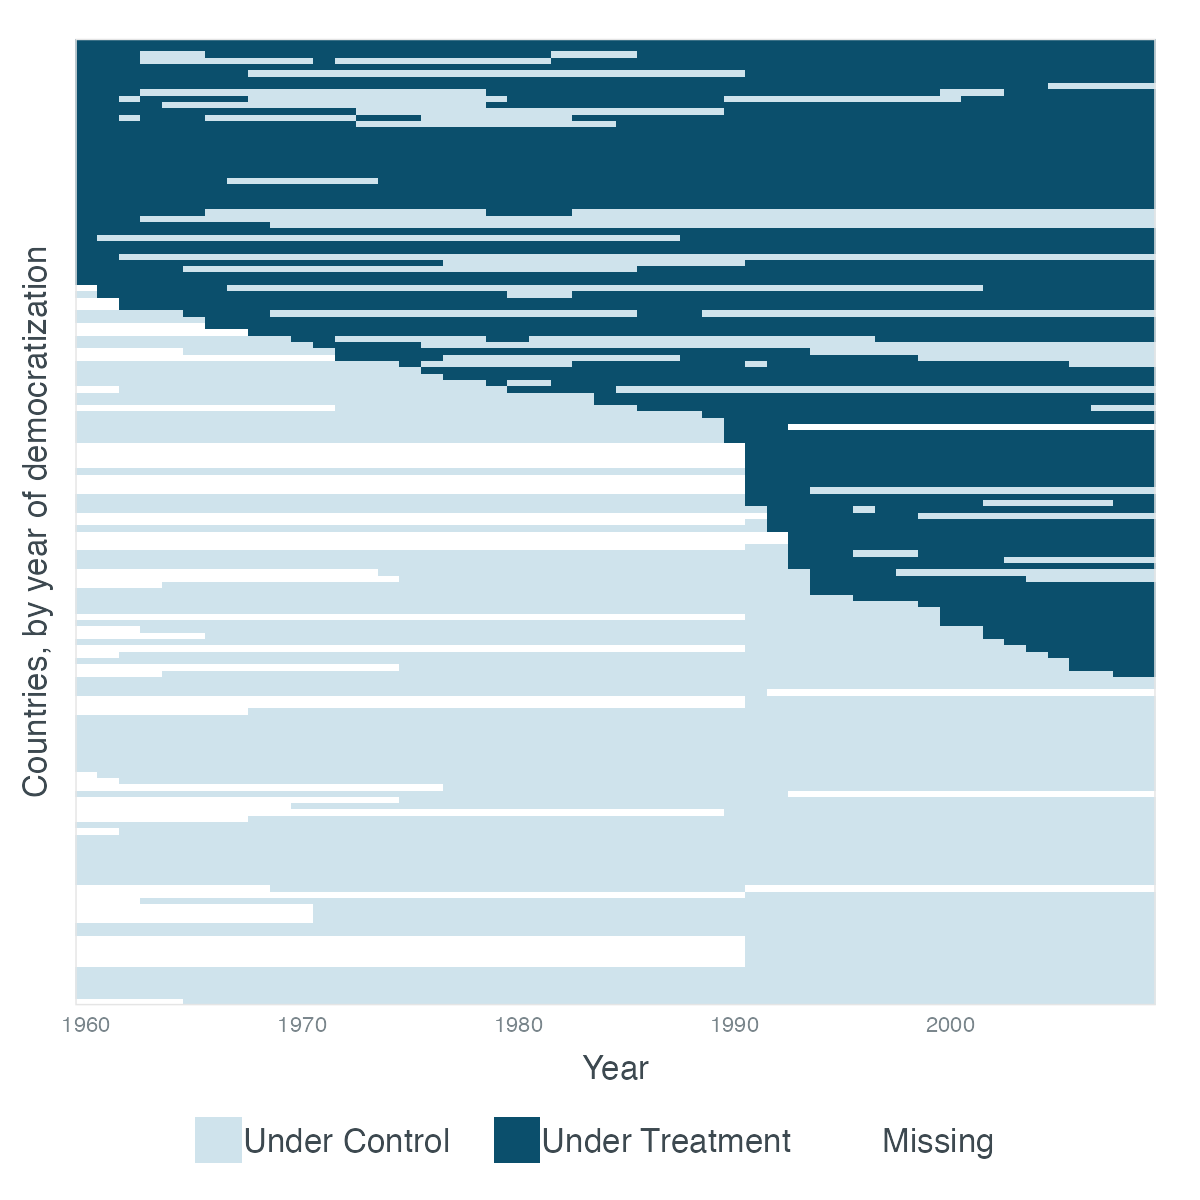
panelView provides four functions: (1) visualize treatment and missingness in panel data; (2) plot variables over time; (3) show bivariate relationships by unit or in aggregate; (4) display multi-way fixed effects as a k-partite graph, identifying components, singletons, and duplicates.
Lecture slides, code and data, free to reuse. All teaching.
The full list is in the CV.